Jekyll2026-10-21T12:11:59+00:00https://narendranag.com/feed.xmlNarendra NagEssays on media, technology, sports streaming, and strategy from a founder and media executive.Narendra NagTen Businesses in an Afternoon2026-10-19T00:00:00+00:002026-10-19T00:00:00+00:00https://narendranag.com/2026/10/19/ten-businesses-one-afternoonThere are ten businesses in a folder on my laptop, and they took one afternoon.
Each one is properly scoped: the market, the buyer, why the incumbent solution fails, where the first hundred customers come from, what it costs to build. They are not prompts or one-line notions but the document you would take into a room.
A system I built produced them, and the obvious reading of that is wrong. The machine did not have the ideas. They came from places I already knew something about — communities I have watched for years, failure modes that have annoyed me personally, markets where everyone has complained about the same unfixed problem in the same forum thread for a decade. The machine did the writing up: the structuring, the sizing, the honest paragraph about why the idea might not work. That part used to take a weekend per idea, which rationed how many ideas ever got past a napkin.
10plans in an afternoon, none of which can be judged from the page
My first instinct was the old one: read all ten, rank them, pick two, bin the rest. I had a shortlist before I noticed what I was doing.
A business plan was never the bottleneck; nobody has failed for lack of a document. The scarce input was taste, knowing which idea is worth a year of your life, and the plan was a proxy for it, a check on whether an idea survived being written down. That check has stopped working. Good ideas used to die unwritten. Now bad ideas arrive with a market section, a go-to-market plan and a confident tone, and a weak idea written up well looks like a strong one until you have spent six months on it.
A shortlist made on a laptop is a prediction of winners from a document, using the signal I have just said cannot be trusted. Ranking ten plans that all read well is a coin toss with paragraphs.
The better move is to stop adjudicating on paper. If a plan costs an afternoon, a small real launch in front of people free to ignore it is not far behind, and it is cheaper than a good guess. What has to be decided in advance is not which idea wins but what failure looks like: what a thing has to show, and by when, or it stops. That gets written down before I know the answer and while I have no stake in it, so I cannot move the line later.
Taste did not disappear. It moved, from guessing which of the ten deserves a year to deciding which do not deserve another week. The folder is not a list to whittle down but a list of things to put in front of people and let them answer.
The useful output of the afternoon is not a shorter list. It is a kill rule, written before I start.
]]>Narendra NagThe Second Client Problem2026-10-12T00:00:00+00:002026-10-12T00:00:00+00:00https://narendranag.com/2026/10/12/the-second-client-problemEvery service business begins the same way, and the problem is that the beginning works.
You do something well for one client. A second client wants the same thing. The obvious move, and on that day with that information the correct one, is to copy what you built for the first and edit the copy. It takes an afternoon instead of a week, the client is delighted, and you have doubled revenue at almost no marginal cost. It feels like the leverage everyone promises you.
Do it eight more times and ten near-identical versions of the same logic are running in ten places, diverging, and a fix to one reaches none of the other nine. The bug you patched for client three is still live for clients one, two, and four through ten, and you will find out which when one of them calls. The margin that looked like it was compounding has been converting into maintenance, and the fix now costs a migration performed on live systems belonging to people who are paying you.
I have watched this happen from the inside more than once, and no single decision in the sequence was wrong.
The trap is that the wrong answer keeps working
That is what makes it a hard problem rather than a stupidity problem. If copying failed at client two, nobody would do it. It fails at client ten, and by then copying is no longer a choice you are making but the shape of the business.
Every incentive points the wrong way at the moment the decision matters. At client two, building the general version costs a week you do not have, to solve a problem you do not yet have, for clients you have not yet won. The general version has no advocate in the room. The specific version has a delighted customer and an invoice.
The correct decision requires acting on a problem that is still theoretical, with time that is scarce, on evidence that will not arrive for a year.
What building it early costs
I tested this on myself, which is the useful thing about being small enough to be your own experiment.
Before I had a single client, I built the general version: a registry with one row per client, holding their configuration — status, where their work should run, which credentials to use, where their alerts go — and one small resolver that every client-facing process calls first to find out who it is serving and whether it is allowed to. There is no client-specific logic anywhere else. A new client is a new row.
It cost a few days that produced nothing demonstrable, with no client asking for it and no revenue attached. It felt like procrastination dressed as architecture until it did not.
What the few days bought is narrow: I can take a second client without touching what the first one is running. It is not a platform, it does not scale to a thousand tenants, and it will need rework at a size I am nowhere near.
What it does is move the expensive work from during the relationship to before it. The plumbing costs the same either way. What changes is whether you pay for it in quiet days now or in a live migration later, with a customer watching.
The version of this that is not about software
I think this generalizes past automation to how a practice becomes a business.
A practice sells the same expensive judgment repeatedly. It scales with the practitioner’s hours and stops when they do. A business sells something that was built once. The transition between the two is this decision, made a hundred times in small ways: when the second client asks for what the first one got, do you copy or generalize?
You should copy at client two, and probably at three. Generalizing too early is its own failure: you build the abstraction before you know which parts vary, and an abstraction built from one example is usually wrong about which axis matters. There is no virtue in a chassis designed for requirements you invented.
But somewhere around the third or fourth time there is a window, when you have seen enough variation to know what differs and not yet made enough copies to make the fix expensive. It is narrow, it does not announce itself, and it closes while you are busy delivering.
The only reliable signal I have found is irritation. When you notice you are making the same edit for the second time and resenting it, the window is open. That resentment is the cheapest available signal that something should be a row in a table rather than a copy of a file.
Most people feel it and keep copying, because a client is waiting and the copy takes an afternoon. That afternoon, repeated, is how a practice fails to become a business.
]]>Narendra NagThe Empty 2002026-10-05T00:00:00+00:002026-10-05T00:00:00+00:00https://narendranag.com/2026/10/05/the-empty-200I built the multi-tenant plumbing this week, before having any tenants to put on it. The alternative is migrating a live workflow out from under a paying customer, and I would rather spend a few days on plumbing than have that week.
The plumbing produced a bug I have thought about more than the plumbing itself: a rejected request that returns HTTP 200 with an empty body.
The setup
Every client-facing workflow first calls a small sub-workflow that takes a tenant ID and answers one question: who is this, and are they allowed to be here? It returns either the tenant’s configuration or a structured refusal — unknown tenant, paused tenant, missing ID, bad config. None of those refusals is thrown as an exception. A paused client is an expected outcome, and treating it as a crash would take down every other client’s traffic with it.
The sub-workflow is three nodes: look up the row, decide, return.
The bug
The workflow engine skips any node whose input has zero items. When the lookup matched no rows — an unknown tenant, the case the resolver exists to catch — the node holding the fail-closed logic never ran, nothing reached the output, and the caller got back a bare HTTP 200 with an empty body.
In a log, a rejected tenant returning 200 OK is indistinguishable from a served one. There is no error to alert on, no non-2xx to graph, no exception to catch. The system reports perfect health while serving nobody. An error page would have been better, because an error page gets investigated.
The fix was one setting: force a placeholder item through on a zero-match query, then filter the placeholder out before deciding whether a real row was found. I re-ran the unknown-tenant case and got a 404 with a structured body.
Why I am writing it down
A week later I hit the same bug in a different workflow. The error handler’s retry-budget lookup had no row on a workflow’s first failure, so the node was skipped and the failure produced no retry and no alert. The first time something broke, the component that tells me something broke was itself broken.
Both cases have the same shape: a lookup that returns nothing, followed by a node that decides based on what the lookup returned. Both passed static validation, because nothing was malformed. The bug exists only at runtime, only on the empty branch, and the empty branch is the one nobody tests.
That two-second call is the whole test. I now run some version of it against every lookup-then-branch I build, and “what does this return when it finds nothing” is the first question I ask rather than the last.
The general form: any system where the negative path is quieter than the positive path will eventually report health it does not have. It errs toward reassurance, which is the direction you are least likely to check.
The full write-up, including the registry design and the four rejection cases, is on the Marain site.
]]>Narendra NagWho Actually Decides Where the Model Runs2026-09-28T00:00:00+00:002026-09-28T00:00:00+00:00https://narendranag.com/2026/09/28/who-actually-decidesEvery organization using AI has decided where the model runs, usually without noticing and almost always for the wrong stated reason.
The public argument is technical: capability against cost, latency against control, the frontier model against the open one you host yourself. Vendors on both sides publish benchmarks. Then the decision gets made in a meeting where no benchmark is mentioned, by someone weighing forces that have nothing to do with tokens per second.
I have been on both sides of that table, arguing for a deployment and living with one, and I want to describe those forces as they are.
The technical case is real, and it is not what decides
The engineering tradeoffs exist. I ran ten business tasks through a frontier model, a 7B model on my own hardware, and a router that chose between them per task. All three scored ten out of ten. The private leg was faster on average and cost nothing per call, because the hardware was already paid for.
That result is narrow — short, well-scoped extraction and classification tasks, one run, one task mix. On harder tasks I expect the frontier model to pull away. But it establishes the useful point: for a meaningful class of real work, capability is no longer the deciding variable. Both options work, so the decision is being made on something else.
Four forces, none of them technical
Regulation, which is a deadline more than a rule. Under GDPR and CCPA a company has thirty days to tell someone what personal data it holds on them. When I built the pipeline that handles those requests, model placement was not a judgment call. Compiling a person’s data in one place and sending that compilation to a public API creates a second copy of the problem the law exists to prevent. So the sensitive step runs on my own hardware, and if that endpoint is unavailable the pipeline refuses and says so rather than falling back. No latency benchmark bears on that decision.
Procurement, which is slower than your roadmap. A frontier API is a vendor relationship, and in a mid-market company a new vendor touching customer data means a security review, a data-processing agreement, and someone’s quarter. The team that self-hosts is often not choosing privacy. It is routing around a purchasing process.
Blame, which nobody says out loud. Behind every placement decision is a person who will have to explain it if it goes wrong. “The data never left our building” is a defensible sentence in a room where things have gone badly. “It was 40% cheaper per call” is not. People who over-weight this are reading their own incentives accurately, which is what I would want them to do.
Values, which are real and rarely admitted. For some organizations keeping data in-house is a statement about who they answer to, not a compliance measure, and they would make the same choice at a cost premium. I no longer treat this as a soft factor. It predicts behavior better than the cost model does.
Why the trajectory framing works better than the choice framing
The mistake is treating this as one decision, made once, at the start, for the whole company. That framing produces paralysis, because it asks people to be right on day one about workloads they have not built yet.
Treat it as a trajectory instead. Start on the frontier, because shipping beats theorizing and most work is not sensitive. As volume grows, some workloads develop reasons to move: a regulator, a contract, a cost curve, a latency floor. Introduce a router that decides per workload rather than per company, and move the slice that earns it.
This framing is better because it survives contact with an organization. Nobody has to be right on day one or defend a company-wide policy against a counterexample. The decision gets made per workload, where the facts live, by someone who can see them.
What I would ask instead
If you are having this argument inside your company, change the question. “Should we be public or private” has no answer at the company level.
Ask which specific workloads, if their contents leaked tomorrow, would produce a conversation you cannot have. Route those privately today and stop arguing about the rest. The remainder is a cost optimization, and that can wait until you have volume worth optimising.
Most organizations find that list shorter than they feared and more specific than they expected. A short, specific list is something you can build against. A company-wide philosophical position is something you can only hold meetings about, and I have sat in enough of those to prefer the list.
]]>Narendra NagWhat the Machine Says About You2026-09-21T00:00:00+00:002026-09-21T00:00:00+00:00https://narendranag.com/2026/09/21/what-the-machine-says-about-youI have spent twenty-eight years in industries organized around being found. It did not occur to me until this summer that the finding had quietly changed hands.
A growing share of buyers no longer start with a search box. They ask a model: a question in prose, answered in prose, with three or four sources folded invisibly into the reply. The buyer never sees the shortlist of twelve blue links, only the verdict assembled from it.
Which raises a question almost nobody at a mid-market company has checked: what does it say about you?
So I built the check. Six questions a real buyer would plausibly ask, put to Claude with live web search on, and a report of exactly what came back — how many answers named you, how many cited your own domain as a source, and which domains got cited instead.
Then I ran it on myself. Named in three of six answers. Cited in zero of six. One answer explained that my firm “appears to be a project centered on recreating and documenting the fictional” language Iain M. Banks invented for his Culture novels — which, given that I named the company after that language, is less a hallucination than a correctly-sourced misunderstanding. Another said plainly that it “wasn’t able to find any reliable, specific information” about a company of that name in the AI space.
79distinct domains cited across six answers — none of them mine
The machine reached for none of my writing. It reached for Wikipedia and the generic AI-consulting roundups, the listicle farms, because those exist in the shape an answer engine wants.
The instinct is to treat that as a marketing problem. I think it is closer to a publishing problem, and an old one. The engine is assembling an answer from whoever explained the category most clearly in the most quotable form. That is not a new game. It is the same game every trade publication has played since the invention of the trade publication, with the reader replaced by something that reads much faster and never clicks through.
Two things follow. The first is that the writing itself is now the distribution — not a funnel toward it. The second is more uncomfortable: the check is free, takes three minutes, and I put off running it for weeks, because there is a particular reluctance to ask a machine what it thinks of you.
It is worth getting over. The report only tells you what is already being said.
]]>Narendra NagTwenty-Seven Years of Writing on the Web2026-09-15T00:00:00+00:002026-09-15T00:00:00+00:00https://narendranag.com/2026/09/15/twenty-seven-years-of-writing-on-the-webBetween July 1 and September 14, the eighth most-viewed page on narendranag.com was “Page Not Found.” It accounted for 3.18% of all views. So, I got Claude to check. All 21 dead addresses people were landing on came from outside, from links to versions of this site that no longer exist.
Some of those addresses ended in .php, which dates them to the WordPress years. Some were bare slugs from a later theme. Following them back turned into an excavation of every place I have published since 1999, most of which I had lost track of. Here’s what those sites looked like, recovered from the Wayback Machine, and what came back with them.
Notepad and Banner Ads
My first website lived at naren.8m.com, built using Dynamic HTML that I was learning. For a while narendranag.com simply redirected there. It was not a blog. It was a set of tutorials for people building their first sites: how FTP works, where to host, how to open a link in a new window with JavaScript, how to position layers in DHTML. The page on designing your own site notes that “most of this site has been made using Notepad!” What I’m proudest of is the alien gif I used on the front page.
naren.8m.com, "Naren's Virtual Network." Captured March 2001.
It was not even the first attempt. A page on that site explains that I had earlier built a site “about me” in DHTML, and that it “went into limbo.” Nothing of it survives. What does survive is the JavaScript tutorial, which ends by asking anyone who reuses the code to “put in a line of code giving me credit.” There is also an article on marketing a website that I reprinted from a newsletter, with its author, Jim Daniels, credited.
Thinking Out Loud
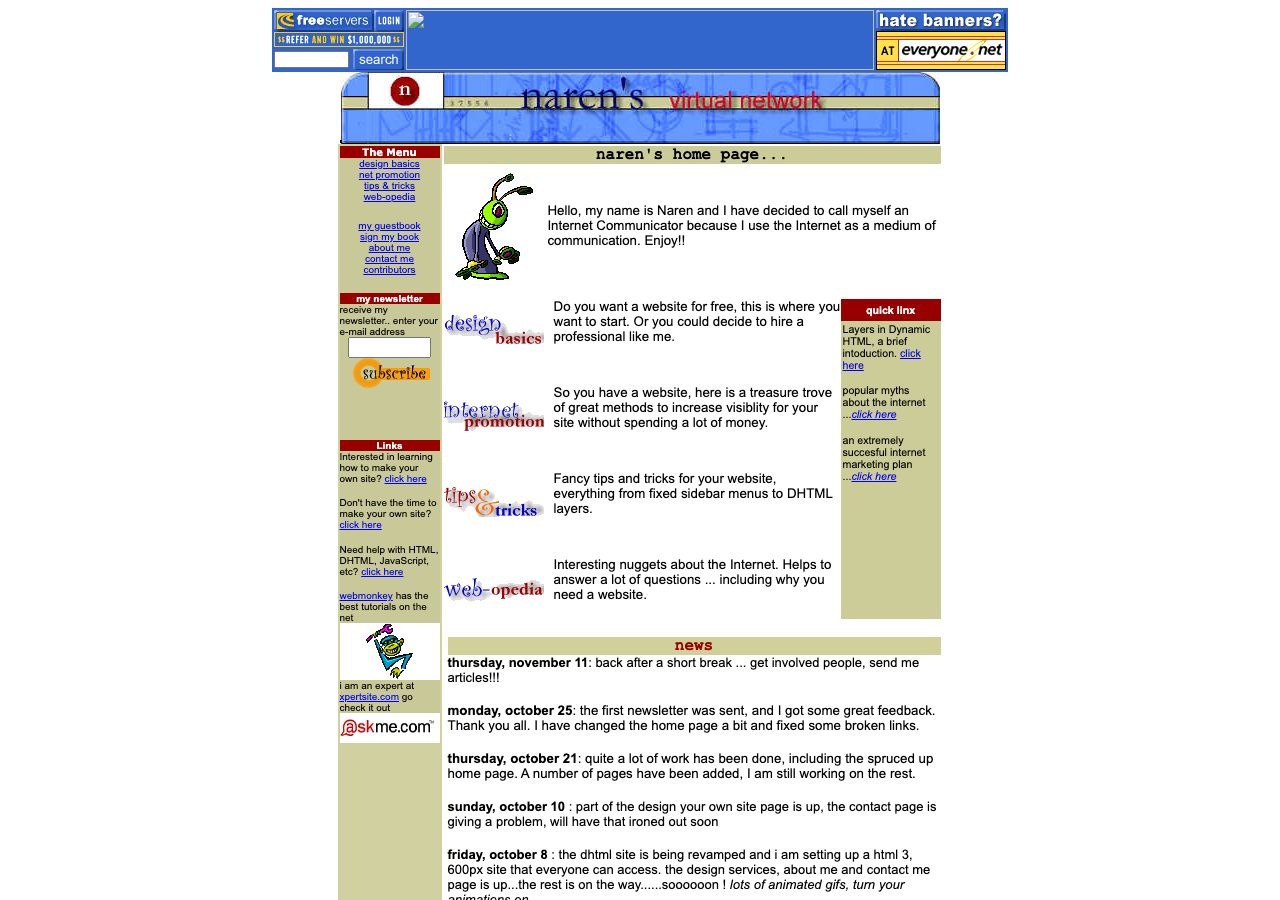
In May 2004 I converted a newsletter I used to run (well, an email list) and started a blog on Blogger called ] t h i n k [. The first post shows how young I was.
tootb.blogspot.com, ] t h i n k [. Captured December 2004.
Sixty posts survive from that blog, between May 2004 and April 2006. Many are a line of commentary and a link to something I had read. Others are reporting from where I was, like the run of posts from Srinagar in April 2005, beginning with Nightlife in Kashmir, written the evening the city’s traders went on strike over VAT. I was a reporter with the Hindustan Times back then, and that reporting assignment to Kashmir led to some great stories (including a massive front page story about an attack that took place while I was there).
Connecting Dots
By 2007 the blog had moved to narendranag.com, run on WordPress, and had the name it would keep for a decade: Connecting Dots. In July 2008 I wrote a post called “Dot dot dot …” to say I was leaving journalism. I had resigned from Mint to take up “connecting the dots” full time, working on business ideas and with a consulting firm. The post ends: “This blog is for fun.”
It stopped being only that in November 2008. The day after the attacks on Mumbai began, I published the first of nine posts in nine days trying to make sense of them, and the blog spent that winter on terrorism, the Indian media’s coverage of it, and the Satyam fraud. None of those pages survived with their design intact. The archive saved the words and lost the stylesheets.
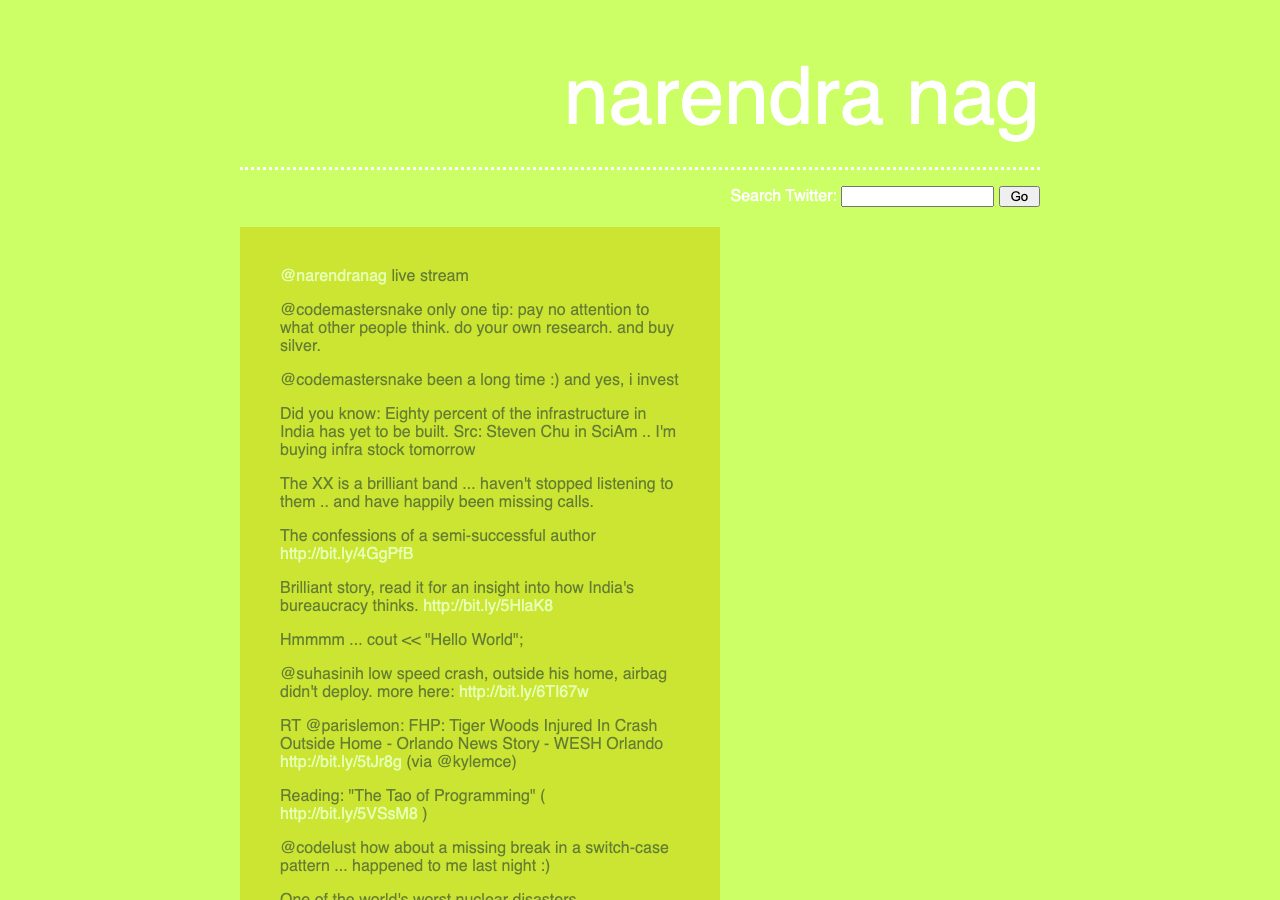
The site changed shape several times. In late 2009 the homepage was a single lime-green stream of my tweets and links.
narendranag.com as a lifestream. Captured November 2009.
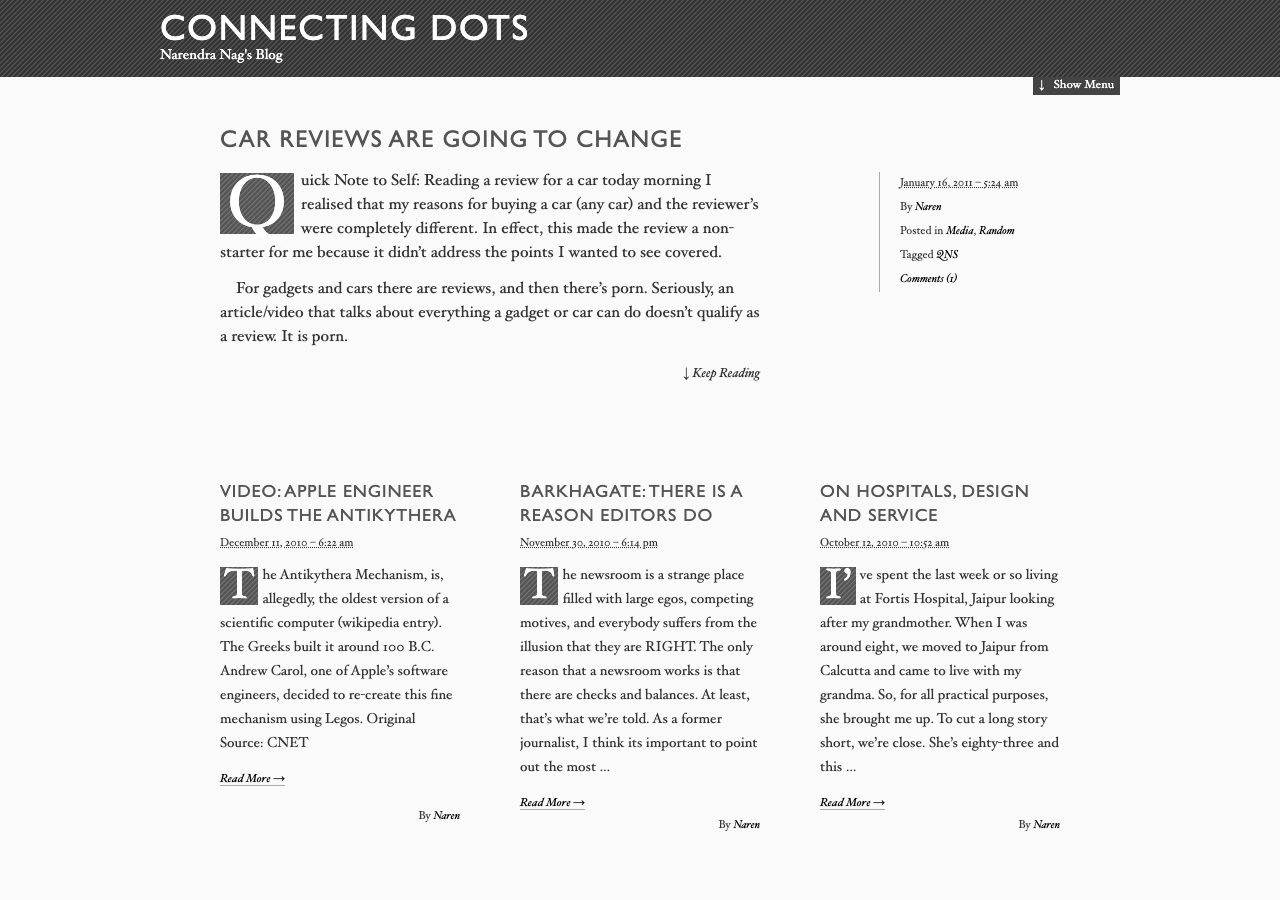
In 2010 I deleted the old blog, started over, and published a new first post that read, in full, “The Blog Is Dead. Long Live The Blog.” By early 2011 Connecting Dots was back, now laid out like a magazine, with a lead story and three columns under it.
Connecting Dots as a magazine. Captured February 2011.
The last posts before a long gap, in December 2012, were about the protests that followed the Delhi gang rape, including “Why I am angry, why I am protesting”. Then I stopped writing, and in June 2013 I let the domain lapse. For most of the following year narendranag.com belonged to someone else. When I got it back I wrote a post called “A Hiatus”: “Much has happened since I last wrote a post — a child, a new home, an election … I let the blog die. After the anger and the activism, I needed a break.”
Connecting Dots after the hiatus. Captured June 2014.
Somebody Else’s Platform
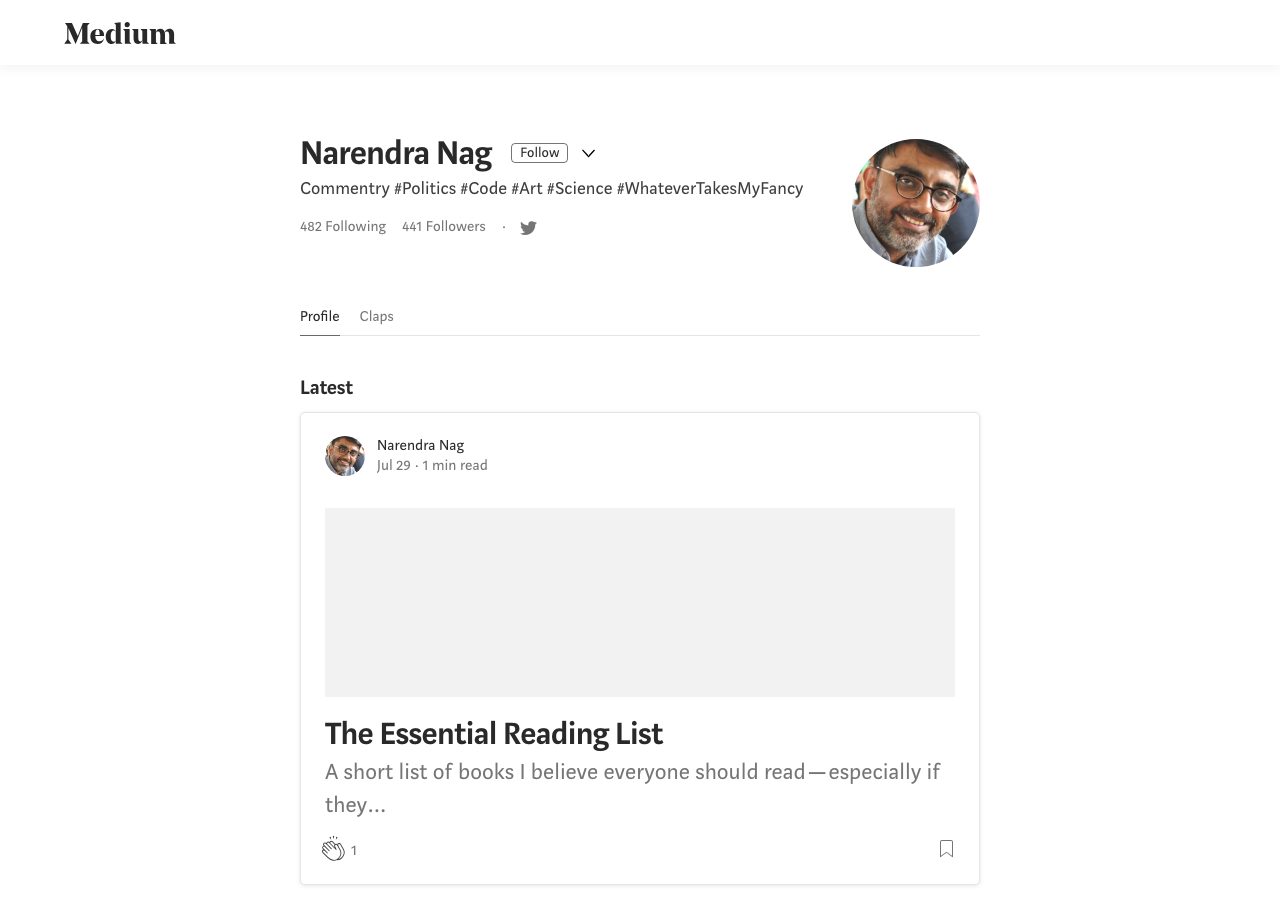
From late 2015 my WordPress posts were syndicated to Medium, and before long Medium was the only place I published.
medium.com/@narendranag. Captured November 2019.The same profile after Medium's own redesign. Captured July 2022.
The Internet Archive has no captures of narendranag.com at all between mid-2017 and mid-2024.
Coming Home
On July 4, 2024 I rebuilt the site on Jekyll and GitHub Pages and wrote a short note about it. It says I would “spend time with Claude and ChatGPT figuring out how to find and pull in the stuff I’ve published over the years into this one place.” The first version was a plain list of posts.
The rebuild on Jekyll. Captured August 2024.
This year the site took its current shape, set like a print journal. The two captures below are the same design, three months apart. The first, from June, says “Writing since 2019.” The second is today, and says “Writing since 1999.”
June 2026: "Writing since 2019."September 2026: "Writing since 1999."
What the Crawler Kept
The plan in that 2024 note took two years to act on and one day to finish. I did it this week with Claude Code, and most of the work was not writing but judgement: which archived page was a post and which was a category listing, which date was the publication date and which was just when a file was uploaded, and which posts were actually mine.
This week the site went from 48 posts to 219. Nine came from naren.8m.com, 60 from ] t h i n k [, 91 from the WordPress years and 11 from Medium. Eighteen of the 21 addresses that used to return “Page Not Found” now lead somewhere. Most dates are exact, taken from the date each blog displayed. The 1999 pieces are accurate to the year and no closer.
I left some posts out. For years I reprinted other people’s work in full: Stratfor analyses, wire stories, newspaper columns, a poem. Those are not here. The one exception is the 1999 marketing article, kept with its author credited because it is part of the record of that first site. The posts that came back cleanly are the ones where I was doing the writing.
None of it survived because I kept it. Of the 171 posts, 160 exist only because the Internet Archive happened to crawl the page, often only once. The other 11 were still sitting on Medium. The hosts were free, the blog was deleted, the domain lapsed, and the platform I moved to was one I did not own. This site is now the only place all of it lives together. Finally.
]]>Narendra NagTen Tasks, Three Ways2026-09-14T00:00:00+00:002026-09-14T00:00:00+00:00https://narendranag.com/2026/09/14/ten-tasks-three-ways“Run AI publicly where it makes sense and privately where it matters” is the kind of sentence anyone can say, and I have said it a lot this year. It sounds like judgment and costs nothing to assert.
So I built the thing that tests it. A harness that takes ten business tasks — classification, extraction, one-line summary, question-answering over a supplied paragraph — and runs every one of them three ways: through the hosted frontier model, through a 7B model on my own machine, and through a router that decides per task which of the two should see it.
Four of the ten cases have fake personal data planted in them: a name with an email and a social security number, a name with a phone number, a bank account number, a name with a date of birth. Those exist to make the router work for its living. Scoring is deterministic — exact or fuzzy match against a gold answer, or the fraction of required keywords present. No model grades its own homework.
One run, on live infrastructure, twenty real HTTP calls, forty and a half seconds:
Accuracy
Avg latency
Cost
Cases leaked
Public
10/10
2730ms
$0.0057
5/10
Private
10/10
1137ms
$0.0000
0/10
Hybrid
10/10
1764ms
$0.0037
0/10
What I will and will not claim
The 7B model matched the frontier model on all ten. That is a statement about these tasks — short, well-scoped extraction and classification — and not a claim about model capability in general. Run it against something open-ended and I expect the gap to reappear.
Private was also faster, 1137ms against 2730ms. I am not going to tell you self-hosted inference is faster; for prompts this short, a hop to my own hardware simply beats a round trip to an API plus its inference time. What it does kill is the assumption I have to argue people out of most often — that private automatically means slow.
The result I would have preferred to leave out
The router’s heuristic for “a name next to a date” fired on a plain invoice. Bill to: Acme Corp… Due date: 2026-09-01. “Acme Corp” looks like a First Last name; the date looks like a date. It routed an ordinary invoice to the private model for no reason.
I am reporting it rather than quietly editing the eval set around it, because it is the same classifier running in production with the same known failure mode. And the direction of the error is the whole point. An over-eager classifier wastes a private call on a boring invoice. It never sends someone’s social security number to a public API.
The failure worth engineering against is the false negative. A harness that hides its own false positives has not earned your trust on false negatives.
Why an instrument beats an opinion
Ten cases is a small set, deliberately. The value is not the scoreboard — run a different task mix and every number moves. The value is that a placement decision now arrives with measurements attached instead of a consultant’s confidence.
I have sat through a lot of meetings where the question of where to run the model got settled by whoever spoke last. This is cheaper than that meeting, and it is right more often.
The full teardown, including the execution log and the scoring code, is on the Marain site.
]]>Narendra NagThe League and the Derivatives Regulator2026-09-11T00:00:00+00:002026-09-11T00:00:00+00:00https://narendranag.com/2026/09/11/the-league-and-the-derivatives-regulatorOn March 19, 2026, Major League Baseball made an announcement with two clauses in it. The first clause was the familiar kind, the kind the industry has learned to skim: the league named Polymarket its exclusive prediction-market partner. Leagues name exclusive partners constantly — official beer, official airline, official cryptocurrency exchange. One more logo on the wall.
The second clause was the strange one. In the same announcement, the league said it had signed an integrity framework directly with the Commodity Futures Trading Commission — the federal agency that regulates derivatives.
A baseball league and a derivatives regulator, signing paper together.
I have been turning that sentence over since the spring. The CFTC exists to police futures on corn and crude oil, swaps on interest rates, options on cattle. It is not a sports agency. It has no gaming division, no problem-gambling fund, no history with a batter’s box. And for the past eight years, when an American sports league signed integrity paper, it signed with state gaming commissions — the regulators of the settlement that built legal sports betting in this country. That is where the relationships were, where the tax deals were, where the leverage was.
So when the biggest of the summer sports signs an integrity framework with a federal commodities regulator instead, it is worth asking what the league knows.
Since 2018, American sports betting has been a state-by-state settlement: 39 gaming regimes, 39 tax arrangements, 39 rulebooks, each one negotiated statehouse by statehouse. Prediction markets run under federal commodities law and route around all of it. The leagues have noticed. And at least one of them has quietly started switching sides.
The Settlement of 2018
In May 2018, the Supreme Court struck down the federal law that had confined legal sports wagering to Nevada. What replaced it was not a national market. It was a settlement — assembled the way American settlements usually are, one legislature at a time.
Each legalizing state built its own regime: its own regulator, its own licensing fees, its own tax rate, its own advertising restrictions, its own self-exclusion lists and problem-gambling funds. New Jersey’s rules are not Pennsylvania’s rules. Pennsylvania’s tax rate is not Iowa’s. An operator that wants national reach carries a license, a compliance operation, and a tax bill in every state it enters — 39 of them now — and simply does not exist in the states that said no.
The leagues’ arc through this settlement was a story in itself. They had fought legalization in court for decades — the 2018 case had the NCAA’s name on it. Then, having lost, they went statehouse to statehouse asking to be paid: an “integrity fee,” a cut of the handle, in exchange for policing their own games. The statehouses mostly declined. What the leagues got instead was quieter and, over time, probably richer — official-data provisions, sportsbook sponsorships, authorized-operator designations. The leagues learned to farm the state map. They did not love it, but they got very good at it.
And the settlement, for all its duplication, was real. It generated real money for state budgets — roughly $3 billion in state taxes in 2024 alone, closing in on a billion dollars a quarter by mid-2025 — and it built the only harm apparatus American sports betting has: the exclusion lists, the advertising rules, the treatment funds financed by the taxes themselves. It took roughly five years to build out to its current footprint.
Twenty-Two Billion Dollars of Not-Gambling
A prediction market does not call what it sells a bet. It sells an event contract — a yes-or-no instrument that trades between zero and a dollar and settles at one or the other — listed on an exchange designated by the CFTC under the Commodity Exchange Act. To a lawyer, it is a derivative, cousin to a corn future. To the person holding “Yankees to win — YES” at 62 cents, it is a moneyline bet in a different font.
The structural difference from a sportsbook explains both the economics and the regulatory posture. A sportsbook is a counterparty: it sets a line, takes your action, and holds the other side of your bet, which is why it employs traders and limits winners. An exchange holds nothing. It matches one customer’s yes against another customer’s no and clips a fee on the way through — the business model of the NYSE, not the corner book. That architecture is what lets a prediction market stand in front of a federal judge and say, with a straight face, that it is a financial market that happens to list sports, rather than a gambling operation that happens to use financial language.
The legal distinction matters because of everything it routes around. A sportsbook needs a license in every state it operates in, pays every state’s taxes, obeys every state’s advertising and consumer rules, and stays out of the states that never legalized. A federally designated exchange needs one registration. Its contracts trade in all fifty states — including the ones where no sportsbook has ever legally taken a wager.
That is not a loophole at the margins of the industry. It is becoming the industry.
On May 7, Kalshi — the largest of the CFTC-regulated exchanges — raised $1 billion at a $22 billion valuation, roughly double what it had been worth five months earlier. Sports contracts reportedly account for about 76 percent of its recent trading volume — a figure I should flag as secondhand, reported rather than audited, but directionally consistent with everything else in view. A company does not double to $22 billion in five months on election markets in an off year. It doubles on games.
And the losses arrived on schedule. Sportico reported in May that retail users had lost more than $100 million on Kalshi’s parlay-style contracts this year alone. Losing money on parlays is the oldest tradition in American sports betting. What is new is that these parlays are not gambling, as a matter of law. They are derivatives positions, held by retail traders, on a commodities exchange.
The trade is the same. Only the regulator changed.
Kentucky, Twice in One Week
The states have noticed what this does to their settlement, and the fight over it has been running all year, in three branches at once.
Congress moved first. On March 23 — four days after the MLB announcement — a bipartisan group of senators introduced a first-of-its-kind bill to ban sports contracts on prediction markets outright. Whatever its odds of passage, read the timing: the federal legislature reaching for a ban within a week of a major league embracing the product.
The regulator moved the other way. On June 10, the CFTC advanced toward allowing most sports contracts on the exchanges it oversees. The agency the senators want to build a wall is paving the road instead.
That alignment is unusual. In most regulatory fights, the industry runs ahead of a reluctant regulator and Congress plays catch-up on the industry’s behalf. Here the polarity is reversed: the federal regulator is the permissive actor, the bipartisan bill is the restrictive one, and the states — usually the laboratories that move first — are the incumbents playing defense. When the referee and one of the teams start moving in the same direction, the other team stops arguing calls and starts filing lawsuits.
And then Kentucky, twice in one week. On June 12, a coalition went to court to block Kentucky’s new 14.25 percent tax on prediction markets. On June 17, Kentucky sued Kalshi and Polymarket. One state, five days apart, litigation running in both directions.
The tax is the tell. A state that levies a 14.25 percent tax on prediction markets is not trying to ban them — it is trying to tax them like sportsbooks, to drag the federal product back onto the state map. And a coalition suing to block that tax is defending precisely the thing that makes the product valuable: that it does not owe the states anything. Strip away the filings and the fight is not about whether Americans may wager on games. That question was settled in 2018. The fight is about which map collects.
This is the second time in a year I have watched a sports-market problem acquire a governmental layer. In the spring it was streaming — an FCC comment docket filling up with thousands of frustrated fans, the living-room vote — and the lesson there was that political layers do not need to win to alter the math; they only need to exist. Betting’s political layer is further along. It has arrived with the machinery already running: bills filed, suits docketed, a federal agency actively choosing a side.
There is a second way to see the 2018 settlement, and it explains why it is vulnerable. It is a bundle. The wager was sold together with the tax, the consumer protections, the advertising rules, the problem-gambling fund — one product, thirty-nine wrappers of obligation. Prediction markets unbundled it: the wager alone, the obligations sold separately, which is to say not at all. Bundles collapse along exactly this seam — someone offers the valuable piece without the overhead, and the overhead’s constituency is left holding the paper.
The Order Flow Pays for the Cameras
The courtroom fight is the loud part of this story. The infrastructure deals are the part that will still matter when the suits resolve.
On June 8 — two days before the CFTC moved on sports contracts — Sportradar announced a data-infrastructure partnership with Kalshi. Sportradar is one of the two companies that sit underneath nearly every legal wager in America, collecting and distributing the official data that prices the markets and settles the outcomes. Polymarket’s MLB deal runs through the same pipes: the March announcement gives Polymarket access to Official League Data from Sportradar, which the release names as MLB’s exclusive global distributor of data for prediction markets. The exchanges are not building parallel plumbing. They are being welded onto the existing stack — the one the sportsbooks built.
The other company in that duopoly made the more interesting deal. On March 17, the rebuilt Pac-12 named Genius Sports the exclusive gatekeeper of its game data for sportsbooks, and as part of the same arrangement is deploying GeniusIQ optical tracking across its football and basketball. Read that deal from the conference’s side. A rebuilt college conference cannot fund national-grade tracking infrastructure out of its media checks. It now has that infrastructure anyway — because the company that sells its data to the betting markets paid to install the cameras.
This is the arrangement I keep circling. Optical tracking is not just a betting input. It is the measurement layer of modern sport — the same category of system that reviews the strike zone in baseball this season and calls offside at the World Cup. The leagues want it for officiating, for coaching, for broadcast. The markets need it to price and settle contracts. And increasingly it is the markets’ money — the order flow — that funds the deployment, down to the college-conference level now. The cameras that adjudicate the game are being paid for by the people wagering on it.
Once you see that, the MLB–CFTC framework stops looking eccentric and starts looking efficient. A league whose measurement layer is financed by wagering order flow has an existential interest in the integrity of that order flow — in seeing the market, in flagging the anomalous position, in having a counterparty who will act. Under the state settlement, that means 39 relationships with 39 regulators of varying sophistication. Under commodities law, it means one desk in Washington with subpoena power over every designated exchange. If you were the league’s integrity office, which map would you choose?
The Ledger, and the Map
A Siena College poll in April found that 27 percent of Americans have an active online betting account, and that 60 percent of bettors report having chased losses. More than a quarter of the country is holding an account, and the majority of the people using them report the signature behavior of gambling harm. This is no longer a story about a product category. It is a story about a population.
I do not bet. It is worth saying plainly — not as a temperance position, but as a disclosure of where I stand while writing about an industry whose growth is the most important business story in sports. What I care about is the machinery. The state settlement, whatever its inefficiencies, built a harm apparatus: self-exclusion lists, advertising restrictions, treatment programs financed by the betting taxes themselves. Federal commodities law was built to protect market integrity, not people. Its customer protections assume a hedger managing risk, not a 24-year-old chasing a parlay at one in the morning. If the order flow migrates to the federal map, the harm apparatus does not migrate with it — it just stops applying.
The institutions filling that gap are telling. Arnold Ventures — a philanthropy — funded a $2 million sports-betting policy hub in January, standing up the research layer that no regulator on either map owns. And as far as I can find, no state gaming regulator has issued any AI-specific guidance for sportsbooks — this in a year when the pricing engines are marketed on their AI. The people building this market are years ahead of the people who would govern it, on both maps, and the distance is widening.
The 2018 settlement took five years to build. The federal end-run could unwind it in two.
The settlement took five years, thirty-nine legislatures, and it pays for itself through the taxes that fund its own guardrails. The end-run needs none of that. The contracts already trade in all fifty states. The CFTC is moving to allow most of them. The largest exchange doubled its valuation in five months on sports order flow. Every commercial incentive in the system now runs downhill toward the federal map — one registration instead of thirty-nine, one tax fight instead of thirty-nine, one regulator whose mandate was written for wheat.
I do not know how fast the unwinding runs, and I am suspicious of anyone who claims to. The Kentucky suits will take years to resolve, the Senate bill may die in committee, and a different commission in Washington could reverse the CFTC’s posture in an afternoon — political layers cut both ways. So here is what I am actually watching. Whether a second league signs integrity paper with the CFTC, because one league is an experiment and two is a pattern. Whether the Kentucky tax survives, because a tax that sticks gives every other statehouse a template for dragging the exchanges back onto the state map. And whether the sportsbooks themselves — the companies that spent eight years and enormous sums buying licenses in 39 states — start acquiring or building exchanges rather than lobbying against them, because that is the moment the incumbents concede that the settlement they paid for is no longer worth defending.
And the leagues — who spent the years after 2018 petitioning statehouses for integrity fees and settling for official-data money — have just shown you where they think this ends. Integrity frameworks are courtship. A league signs one with the regulator it expects to be living with for the next decade. For eight years that meant gaming commissions in Trenton and Harrisburg and Frankfort. In March, baseball signed with the derivatives regulator in Washington.
A partnership announcement on the surface. Underneath, a change of address.
]]>Narendra NagThe Counting Problem2026-09-07T00:00:00+00:002026-09-07T00:00:00+00:00https://narendranag.com/2026/09/07/the-counting-problemIn 2013 the Indian government’s official records put malaria deaths in the country at 440. The government’s own medical certification of cause of death report put them at 5,428. A committee of the Indian Council of Medical Research put them at 40,297. The Lancet put them at 205,000.
I came across those four numbers sitting next to each other while running a stakeholder audit for Malaria No More in India, and the finding that mattered was not a health finding. State funding was allocated against reported incidence. The count was wrong by somewhere between ten and a hundred times, so the funding was wrong, so the delivery was wrong. Nobody in that chain was lying. Each of them was reporting the number their instrument produced.
The sharpest single piece of evidence in the study came from an accredited social health activist in Junagadh Block, Kalahandi, in Odisha. She was paid between twenty-five and seventy-five rupees for malaria work and better rates for maternal reporting, which meant she was financially rewarded for spending her time elsewhere and quietly penalized for finding malaria. A national policy adviser was interviewed for the same study. The village health worker had the finding.
What a group has agreed to count
That audit is the clearest example I have of the only thing I have ever really worked on, which is the gap between what drives an organization and what it reports.
A newsroom that counts page views produces one kind of journalism. A newsroom that counts corrections produces a different one, with the same reporters. A company that counts booked pipeline builds a different sales organization than one that counts the time between a customer’s problem and its resolution. Once the counting is settled, most of the behavior is settled with it, whatever the values poster in reception says.
Every organization I have worked in has a gap between the list of things that actually move it and the list of things it reports every month. Every one of them believes its own gap is smaller than it is.
My CV reads as though I have had four or five careers. Journalism, advertising, a consultancy advising boards, companies of my own, streaming. For a long time I picked whichever one a room seemed likeliest to find interesting and left the rest out, because the alternative was explaining a résumé that looks like four people took turns with it.
They were the same job, and it took me too long to see it. Working out what is worth counting is an empirical problem. Making the count legible to the people who have to act on it is a storytelling problem. Building the instrument that does the counting reliably, without you in the room, is an engineering problem. Drop any one and you get a failure I now recognize on sight: a finding nobody acts on, a story nobody can verify, a machine measuring the wrong thing to four decimal places.
Twenty-eight years of that, in four versions.
In a newsroom, the gap was between what mattered and what was countable. I was a journalist from 2001 to 2007, and the honest position for most of it was that nobody knew what was working. Ratings arrived late and described the wrong thing. Then the internet arrived with numbers attached to everything, and we found that the countable thing and the valuable thing were not merely different but could be opposed. A story that mattered and a story that traveled were two different products, and only one of them showed up in the report.
At Publicis, the gap was the product. Six years, most of them spent working out what a marketing dollar actually bought in a market where the tooling changed faster than the accounting could follow. I grew the group’s digital practice in India from one office to four and from ten people to more than a hundred. What we were really selling, under the campaigns and the media plans, was a defensible answer to a question the client’s finance director kept asking.
At Xynteo, the gap moved up a floor. As Chief Digital Officer I sat with executive teams at some of the largest companies in the world and asked whether their strategies were working. Almost none had built the instrument that would tell them, and not because they were unserious. Building it was expensive, slow, and required a kind of attention that quarterly life does not protect. The strategy got measured by whether it survived contact with the board, which measures something, just not the thing.
Then it became my own problem. I have started four companies and sold two of them. The first, in 1998, ran on a content management system I wrote by hand. The most recent was Laminar, which let media companies launch a full streaming service — backend through monetization and analytics — in eight weeks rather than years, and which was acquired in December 2023. What running a company teaches you about this is that the scarce input is not capital or engineering. It is knowing which of the forty things on the roadmap actually moves the business, when all forty have advocates and three matter.
What changed this year
For twenty-eight years, the reason organizations did not measure the thing that mattered was cost. The instrument meant an engineer, a data pipeline, a quarter of someone’s roadmap, and a political fight about whose number was right. So it did not get built, a proxy stood in for the truth, and everyone agreed not to look too hard at the seam.
That cost has fallen far enough to change the decision. I spent this summer building the kind of instrumentation that used to require a team, and the marginal cost of running it lands at fractions of a cent. A researched dossier on a company, a few cents. Extracting the fields from an invoice, about a penny. A harness that puts ten business tasks through three routes — a hosted frontier model, a small model on hardware I already own, and a router choosing between them per task — scoring each on accuracy, latency, cost, and what left the building: one afternoon of setup, then effectively nothing per run.
When the instrument cost a quarter of an engineering roadmap, “we don’t measure that” was a resource decision. It is now a choice.
What did not change
The obvious conclusion, that we are about to get much better at measuring things, is premature. Cheap instruments do not produce good measurement any more than cheap cameras produced good photographs. They produce more measurement, most of it aimed at the wrong thing.
The hard part was never the building. It is knowing which question is worth an instrument, which proxy is lying to you, and which number an organization will actually act on when it arrives. That is judgment, and judgment has not got cheaper by a cent. It has become more valuable, because there is now nothing standing between a confident wrong idea and a working implementation of it.
I know the price of getting that wrong, because I have paid it. In 2019 my company published seat assessments for Uttar Pradesh, built from models that scored hope, fear, aspiration and resentment. The assessments were badly wrong. The models had been signaling that fear and resentment should be weighted much higher than I had set them, and I overrode them, because I did not believe anger was running that hot. The signal was in the data and I discounted it because it did not match my read of the country.
That is why every system I build now logs a human override with a written reason. The failure that costs you is never a broken instrument, because a broken instrument gets found. It is an instrument that is right in a direction you find implausible, which is precisely the moment it is easiest to talk yourself out of.
So the useful version of the question has changed shape. It used to be can we measure this, which has an engineering answer and no longer costs anything to obtain. It is now should we, and will anyone do anything differently when the number arrives, which never had one.
Twenty-eight years, one question, and for the first time the instrument is not the expensive part. The choosing is, and the choosing is the work I intend to spend the next twenty-eight years on.
]]>Narendra NagThe Labor War That Didn’t Happen2026-09-04T00:00:00+00:002026-09-04T00:00:00+00:00https://narendranag.com/2026/09/04/the-labor-war-that-didnt-happenThe robots came for the referees, and the referees signed a seven-year deal.
For a decade, the prediction wrote itself. Every Hawk-Eye camera, every tracking chip, every automated strike zone was supposed to be a fuse — sooner or later, the officials’ unions would dig in, and sports would get its first proper labor war over automation.
Here is what actually happened. On May 8, NFL referees ratified a new collective bargaining agreement by a vote of 116 to 4. Seven years. The vote ended the league’s preparations to field replacement officials — so this was a real standoff, with real leverage on the table — and it landed the spring after the NFL’s first season of camera-based virtual measurement league-wide, the system that retired the chain gang’s judgment on first downs. If automation was a flashpoint in that negotiation, nobody reported it.
116–4NFL referees' vote to ratify a seven-year CBA, May 2026
I see this as the arithmetic of a workforce that looked at the machines and asked for a longer contract.
Baseball ran the same experiment and got the same result. MLB’s umpires accepted the automated ball-strike system inside a routine five-year CBA, agreed before the 2025 season — Rob Manfred had said plainly that the machine was “a term and condition of employment,” a thing the union would have to sign off on, and sign off it did. The machine that grades the profession’s defining judgment call entered the sport as contract language, not as a strike threat.
And the people working under the machines keep declining to play their assigned role. In June, the Guardian interviewed Micheal Barwegen, a World Cup assistant referee working under semi-automated offside. “The computer has to think, and it’s super fast, but [on the field] it feels like forever,” he said — a man describing a colleague, not a rival. One that is slower than he is, more certain than he is, and willing to take custody of the calls no human eye can make.
The labor fight that did happen this season was about money. Tennis players pressed for a bigger share of prize money at the very Wimbledon that had automated away roughly 300 line judges’ jobs the year before. The protest was not for the line judges. Nobody marched for the line judges. The players wanted a larger cut of the tournament’s revenue — a tournament that now, incidentally, employs fewer people to stage.
The NFL season opens next week with its officials locked in for seven years. The NBA has already said out-of-bounds calls are headed for automation, and the tracking cameras have been installed league-wide since 2023. When its referees next sit down, the bargaining will be over data and money — who owns the tracking record, who gets paid for the precision — not over whether the machine gets a whistle.
Automation did not beat labor in officiating. It paid the survivors and skipped the fight.
![tootb.blogspot.com: Blogger's stock template, a centred column under the title ] t h i n k [](/assets/img/evolution/2004-tootb.jpg)